BrightonSEO October 2026 Takeaways: AI, Bias & Trust

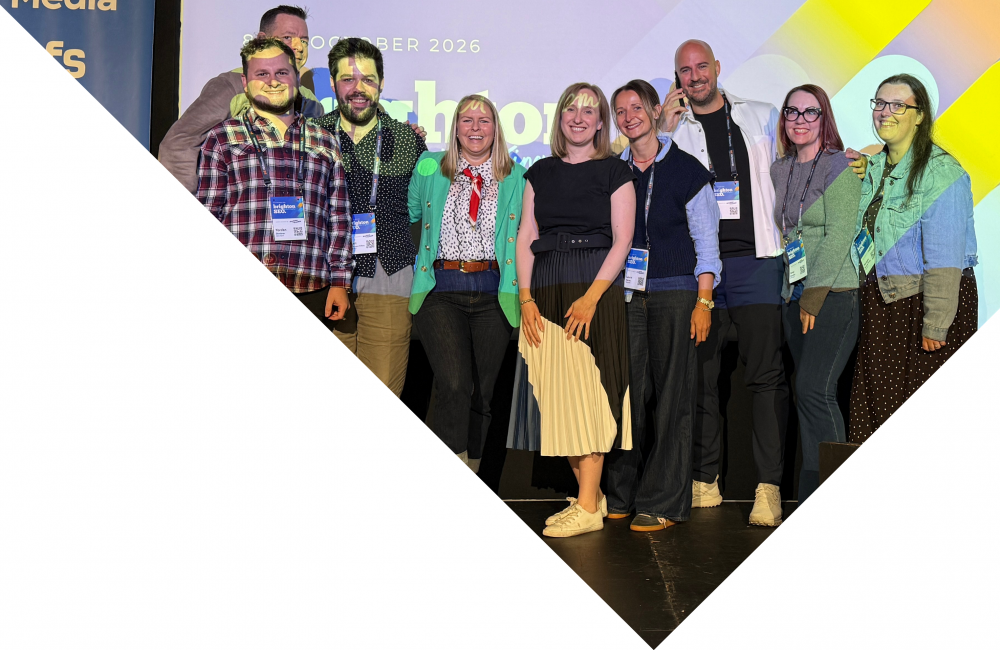
BRIGHTONSEO FEELS A LOT LIKE BRIGHTONAI THESE DAYS.
AI had plenty of whole tracks to itself at BrightonSEO this October - GEO and AEO, Understanding AI Search, AI and Brand Citations, Agentic and Vibecoding - and it crept into most of the other 161 sessions too, from Digital PR and local SEO to a talk on site migrations. That's a fair reflection of where people are, with 47.1% of people now using AI search tools at least sometimes (SearchPulse Q3 2026).
But for all that airtime, I came home with lots of interesting experiments and very little agreement on what good looks like. If I'm honest, I think that's a healthy place for the industry to be right now, as long as nobody pretends otherwise.
THE BIGGER PRIZE IS WORK NOBODY COULD DO BEFORE.
Jeremy McDonald's session, "From Gut Checks to Guardrails: Deploying Trustworthy AI for Marketing QA", argued that the most valuable thing AI gives a team is work that was never viable before (too slow, too expensive, or needing skills nobody in the room had). Plenty of the practical AI talks were about doing today's work faster, and Jeremy was clear that cheaper and faster is the smaller of the two prizes.
The guardrails part is where he jumped into practical implementation. He used a structured prompting framework (RICCE) to write agentic evals - small AI checks that sit at each stage of a multi-step process and score the output against criteria agreed before any work starts. So a draft that drifts from the brief, or a data pull that comes back half-empty, gets caught at the step where it went wrong while it's still cheap to fix, and every stage has a written definition of good that a person can read, argue with and update - which is what gets a team trusting new kinds of work enough to put them in front of a client.
This focus on observability is an exciting development that the industry is shifting towards - especially as tools like Claude Code now contain OpenTelemetry signals that can trace actions, decisions and behaviour in a much more targeted and structured way.
NOBODY HAS THE PLAYBOOK YET, INCLUDING HOW TO DESCRIBE YOUR DATA.
There's no agreed best practice for AI search yet. Gijs de Groot warned that some AI optimisation tactics could hurt your traditional rankings, and Tom Rudnai's title ("Your AI Visibility Metrics are Lying to You") gets at the measurement problem underneath it all - prompt tracking, citation counts and visibility scores each measure something a bit different, and they often get reported as if they were the same thing.
The same uncertainty runs through how we describe data to machines. Dixon Jones made the case for entity maps, Judith Lewis and Laura Iancu both covered what schema (the structured markup that labels what's on a page) does in modern search systems, and the corridor conversations were full of ontologies, markdown versions of pages and llms.txt (a proposed file pointing AI tools to a site's most important content). They're all attempts at what the data world calls an ontology (describing what things are and how they relate), and nobody can tell you yet which ones the models consume and reward.
Until there's evidence, I'd prioritise the formats that already help traditional search and your own data, like schema and clean entity relationships, and treat the more speculative ones as tests with a measurement plan attached.
MODEL BIAS IS THE GAP IN MOST AI VISIBILITY RESEARCH.
His headline example was software, where GPT 5.6 Luna gave SOC 2 compliance (an independent audit of how a company protects customer data) a huge amount of weight in its recommendations. And from that signal data he built a predictor that matched the model's choice 89% of the time (Tom Wells, Vaer, BrightonSEO October 2026).
If a model weights SOC 2 that heavily, then whether your compliance is clearly stated, easy to find and backed up on third-party sites becomes a generative engine optimisation (GEO) question as well as a sales one. I'd expect those preferences to move between models and between releases of the same model, so it's testing you'd want to rerun each time one changes.
FOUNDATIONS GOT THE MAIN STAGE.
Accessible websites and well-organised data are what both AI agents and serious analysis depend on, and both got main-stage time this year. Friday opened Auditorium 1 with a full block on accessibility, including Damien Robert and Tania Gerard on how sites people can't use become sites search and AI can't trust. Agents have got a lot more people thinking about the layer where humans and machines meet a website, and many browser agents find their way around a page using much the same structure screen readers rely on - labels, roles, headings and accessible names. So a site built properly for assistive technology is most of the way to being usable by an agent, which is a big part of what we look at in our AI agent readiness audits.
Accessibility is the comfortable end of a harder problem, though. People and machines often want information in different shapes: a person usually wants the curated, summarised version with the detail a click away, while a model or agent is better served by the full granular data (every spec, every price tier, every certification) in a structured format, and the more complex the data gets, the further apart those two versions drift.
The obvious fix is to serve each audience its own version, but Google has a name for that in its spam policies: cloaking, presenting different content to users and search engines to manipulate rankings, which can mean a site ranks lower or doesn't appear at all. Markdown copies of pages served only to AI crawlers feel uncomfortably close to that line to me (intent is part of Google's definition, but I wouldn't want to be the test case), so for now the workable route is one page carrying both layers - curated copy for the reader, with the granular detail in schema, tables and expandable sections.
The data talks came at foundations from the other side, with BigQuery (Google's cloud data warehouse), user journey analysis and MeasureFest sessions on server-side tracking and consent cropping up across both days. All of it depends on owned, joined-up data being in place before you need it, and some of it can't be backfilled - Google's own help documentation says the Search Console bulk export starts with data from the day you set it up, so every month you wait is a month of history you won't get back.
PEOPLE DON'T TRUST AI, AND THEY USE IT ANYWAY.
Our own SearchPulse research shows the same pattern. Nearly 35% of people don't fully trust the results AI gives them, and yet among the 26.9% who use ChatGPT regularly, 61.2% value its ease of use and 56.9% prioritise quick results (SearchPulse Q1 2026, p.5).
BJ Fogg's behaviour model explains why. Behaviour happens when motivation, ability and a prompt line up, and Fogg's own finding is that making something easier shifts behaviour more reliably than making people want it more. Trust sits on the motivation side and AI scores poorly there, but it wins so heavily on ability (fewer searches, fewer tabs, less reading) that people clear the bar even with a bit of verification added on top. (Becky Simms' Friday talk on zero-click psychology went much deeper on this, using the same SearchPulse data.)
For your business, that makes the verification step the moment to be present for: the source the AI cites, the review site someone opens to double-check, and the page that confirms the answer.
KEY TAKEAWAYS FROM BRIGHTONSEO OCTOBER 2026.
- There's no agreed playbook for AI search yet, so treat confident claims (your own metrics included) with care.
- AI's biggest gains come from work you couldn't do before, and agentic evals at each step make that work trustworthy.
- Model bias testing shows which signals a model rewards in your category, which gives you something concrete to fix.
- Separate content for people and machines risks cloaking, so build pages with a curated layer and a structured one.
- Accessible sites and owned, joined-up data underpin both agents and analysis, and some data can't be backfilled.
People use AI they don't trust because it's easier, so be visible where they check the answer.
If any of this has you wondering where your business would start, whether that's testing what models prefer in your category or getting your data foundations in place, talk to our AI search team and we'll work through it with you.
Contact Us
MEET THE AUTHOR.
MATT GREENWOOD-WILKINS
Matt is a data and spreadsheet nerd. Having worked in data pipeline engineering, business intelligence and data analysis - he helps us manage and understand data to generate interesting and actionable insights. He helps to drive efficiencies both internally and for clients, creating innovative solutions using automation, machine learning and AI.
More about Matt